Gemini 4 Argon Explained for Humans: What a New Model Race Means for Students, Writers, and Teachers
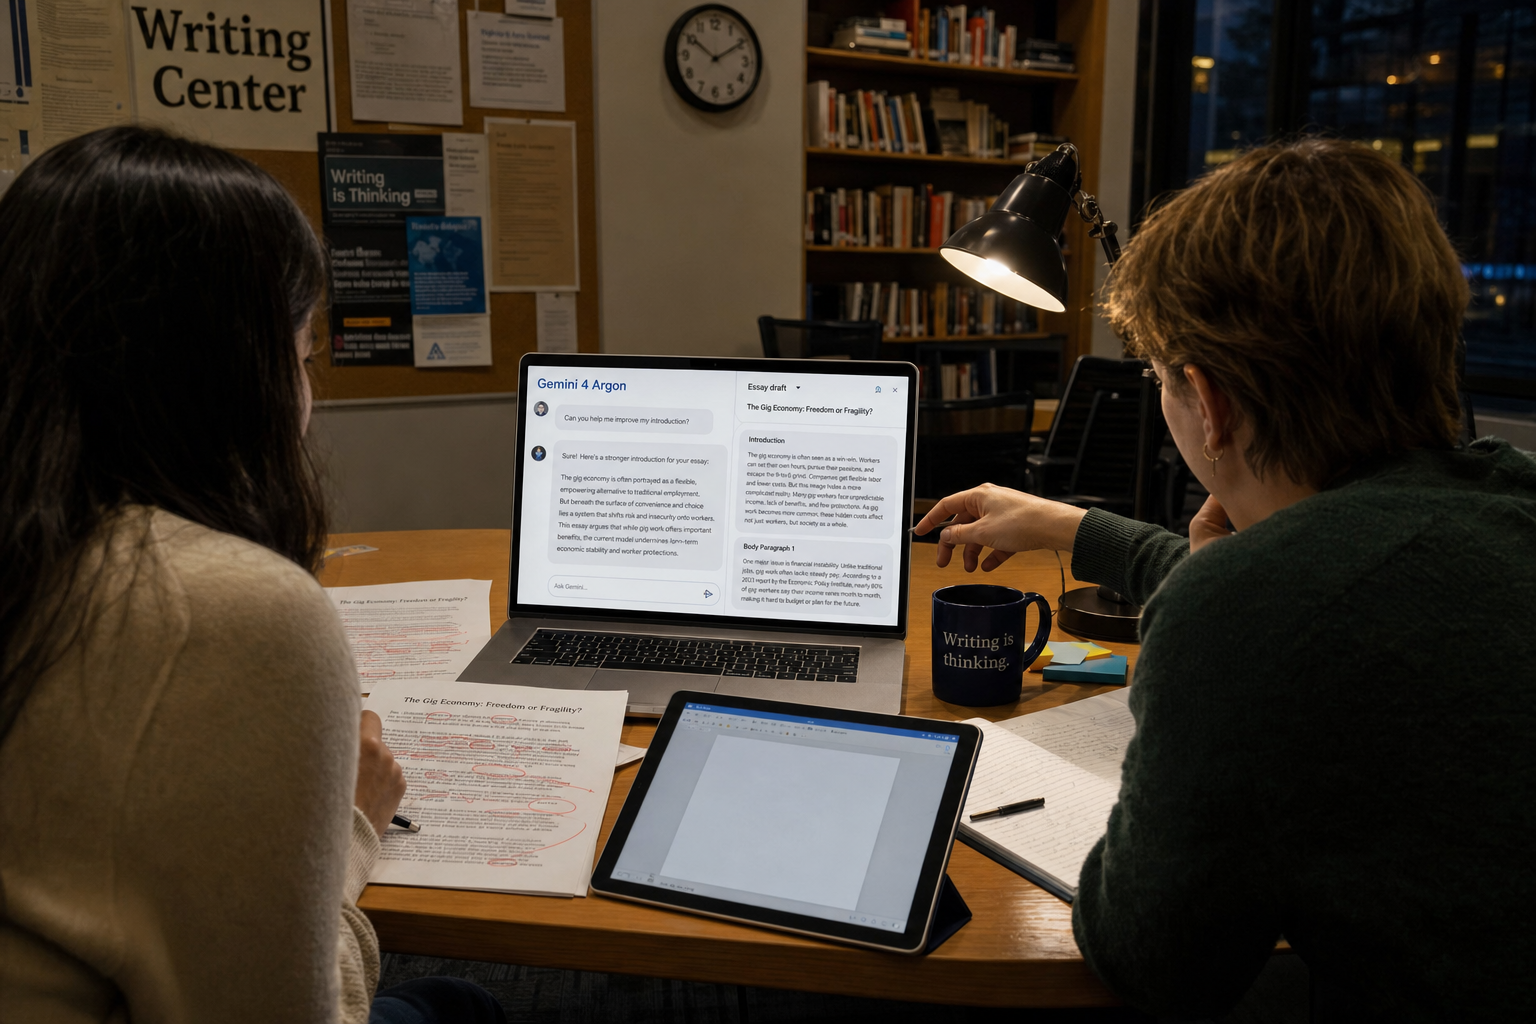
Gemini 4 Argon is the latest model name drawing attention in AI circles. At the time of writing, much of the public conversation is being driven by early reports, online discussion, and benchmark claims rather than a full, settled picture of everyday performance. Even so, the interest is easy to understand. When a major model improves, the change does not stay inside tech forums. It quickly reaches search tools, writing assistants, study apps, and classroom software.
That is why this matters beyond the AI industry. The real debate is not whether Gemini 4 Argon can score higher on technical tests. It is whether a new model race will make learning and writing more reliable, or simply more dependent on systems that still produce confident mistakes. My view is simple: for students, writers, and teachers, the important question is not “Is it smarter?” but “Is it more trustworthy, more useful, and easier to control?”
What we actually know, and what we do not
The name “Gemini 4 Argon” is now part of a wider pattern: every major AI company is pushing new model versions faster, and each release is framed as a meaningful leap. That much is clear. What is less clear, unless and until full documentation and broad independent testing appear, is how large the leap really is in normal use.
That distinction matters. A model can look impressive in demos and still struggle with basic tasks people care about: following instructions exactly, keeping facts straight across long documents, showing where claims came from, and staying consistent from one answer to the next.
So the fair position is this: take the reports seriously, but do not mistake early excitement for proof. In AI, capability claims often arrive before ordinary users get enough time to test the product under pressure.
Why this model race feels bigger than a product update
For most people, a new model is not just a new chatbot. It becomes part of the software they already use. A student may meet it inside a note-taking app. A teacher may see it in lesson planning tools. A writer may use it through search, transcription, or document editing. In other words, many people will not “choose” Gemini 4 Argon in a clear, informed way. It may simply arrive inside their workflow.
That is the first reason this race matters. The second is speed. Schools, publishers, and workplaces are being asked to adapt while the products keep changing. Policies on citation, cheating, privacy, and authorship were already hard to write. A faster model cycle makes them harder.
This is also where the tension becomes real. Better models can lower barriers for learners and save time for professionals. But each jump in convenience can also deepen bad habits: less checking, less original drafting, less patience with difficult reading, and more quiet reliance on a tool that may still be wrong.
For students, the upside is real
If Gemini 4 Argon is genuinely better at reasoning, instruction-following, and long context, students could feel the benefit quickly. A stronger model can explain a concept in simpler language, generate practice questions, compare two arguments, turn notes into a revision guide, or give feedback on structure and clarity. For non-native English speakers, that support can be especially valuable.
Used well, this kind of system can act as a study aid, not a replacement for study. It can help a student find the gap in their understanding faster. It can make office-hour questions more precise. It can reduce the fear of the blank page.
That promise should not be dismissed. Many students already struggle with overloaded classes, uneven feedback, and limited one-to-one support. Better AI tools can help fill some of that gap.
For students, the risk is not just cheating
The obvious concern is academic dishonesty, but that is not the only problem. A more fluent model can produce cleaner mistakes. It can make weak arguments sound polished. It can give an answer that looks complete enough to stop further reading. That is dangerous in subjects where the process matters as much as the final response.
There is also an access issue. If the best version sits behind a paid tier, students with more money may get better study support, better editing help, and faster feedback than students without it. That does not create intelligence gaps, but it can widen performance gaps.
The practical rule for students is still the same, even if the model improves:
- Use it to clarify, quiz, and organize.
- Do not use it as your final authority on facts.
- Check claims against class materials and reliable sources.
- If a teacher requires disclosure, disclose.
- If you cannot explain the answer yourself, you have not learned it.
For writers, speed will improve before certainty does
Writers are likely to benefit early from any serious model upgrade. Better summarization, better handling of transcripts, better structural suggestions, faster background research, and stronger adaptation to different audiences can all save hours. For content teams, journalists, marketers, and independent writers, that matters.
But here too, the main burden shifts rather than disappears. If Gemini 4 Argon produces smoother drafts and more plausible source summaries, then the cost of failing to verify becomes higher, not lower. A polished falsehood is harder to catch than a clumsy one.
There is also the problem of sameness. As models get better at “good enough” prose, more writing starts to sound professionally tidy but mentally thin. The facts may be acceptable. The structure may be clean. The voice may disappear.
For writers, the key question is not whether the model can draft. Most can. The key question is whether it helps produce work that is still distinct, accurate, and accountable.
For teachers, the model race could reduce admin and increase pressure
Teachers may gain some of the most practical benefits from stronger AI tools. A capable model can generate differentiated lesson variations, create quiz drafts, rewrite instructions for different reading levels, suggest discussion prompts, and help with routine communication. That is not a small gain in a profession already stretched by time.
Yet stronger tools also create new pressure. If AI can produce feedback drafts in seconds, institutions may start expecting faster turnaround without reducing other workload. If students use better models, teachers face a harder task in designing assignments that still reveal genuine understanding. If school systems adopt AI features quickly, teachers may be asked to trust software before they have been trained to judge it.
This is why the teacher question is not just “Can it help me?” It is also “What new responsibility does this create?”
- Who checks accuracy in AI-generated materials?
- How are student data and prompts stored?
- What use is allowed, and what use must be disclosed?
- What happens when the tool gives biased, incomplete, or fabricated content?
Without clear answers, convenience can turn into hidden risk.
Benchmarks matter, but they are not the main story
To be fair, benchmark improvements are not meaningless. Technical gains often do translate into real benefits: fewer errors on structured tasks, better multilingual support, improved coding help, better context handling, and more stable tool use. People who follow AI closely are right to care about progress.
But benchmark wins are not the same as user trust. A model can improve on tests and still fail in a classroom, a newsroom, or a workplace where citation, consistency, and accountability matter more than raw cleverness.
That is the counterpoint many AI enthusiasts understate. The model race is no longer just about reaching a new peak. It is about whether these systems become dependable enough to deserve deeper integration into ordinary work.
What everyday users should actually look for
If Gemini 4 Argon becomes widely available, people should judge it by a stricter set of questions than “Is it better than the last one?” These are the tests that matter in real life:
- Does it make fewer factual mistakes?
- Can it show sources clearly and accurately?
- Does it follow instructions without drifting?
- Can users edit, steer, and challenge its output easily?
- Is it safe to use with sensitive school or work material?
- Is the price reasonable for the value it adds?
- Does it work well for non-native English users?
Those questions sound less exciting than benchmark charts. They are also far more useful.
The position that matters now
My position is not anti-model and not anti-progress. Stronger AI systems can help people learn faster, write better drafts, and manage heavy workloads more sensibly. That is the promise, and it should be taken seriously.
But a new model race becomes a public problem when speed outruns trust. If Gemini 4 Argon is mostly a leap in capability, that is notable. If it is also a leap in transparency, reliability, and user control, that is important. Those are not the same thing.
Students do not need a tool that sounds smart. They need one that helps them understand. Writers do not need a tool that fills space. They need one that supports reporting, thinking, and revision without weakening standards. Teachers do not need more pressure disguised as automation. They need tools that save time without creating new uncertainty.
What to remember when the next model name starts trending
Here is the practical takeaway: do not judge a new model by the loudest claims around it. Judge it by the quality of the work it helps you produce, the errors it still makes, and the amount of checking it still requires.
Gemini 4 Argon may turn out to be a meaningful step forward. It may also be another reminder that capability is easier to improve than trust. For students, writers, and teachers, that is the real story of the current model race. Better outputs are useful. Better judgment is still non-negotiable.